| Hardware Metric | Host PC (NVIDIA GTX 1650 4GB) | Edge Mobile (realme 9 Pro+ / Dimensity 920) | Scientific Significance |
|---|---|---|---|
| Target Model Evaluated | qwen2.5:1.5b (Q4_K_M) | qwen2.5:1.5b (Q4_K_M) | Identical parameter weights & quantization |
| Runtime Inference Engine | Ollama v0.34.4 (cuBLAS CUDA) | llama.cpp ARM64 CLI (6 CPU Threads) | Dedicated GPU vs ARM Neon Vectorized CPU |
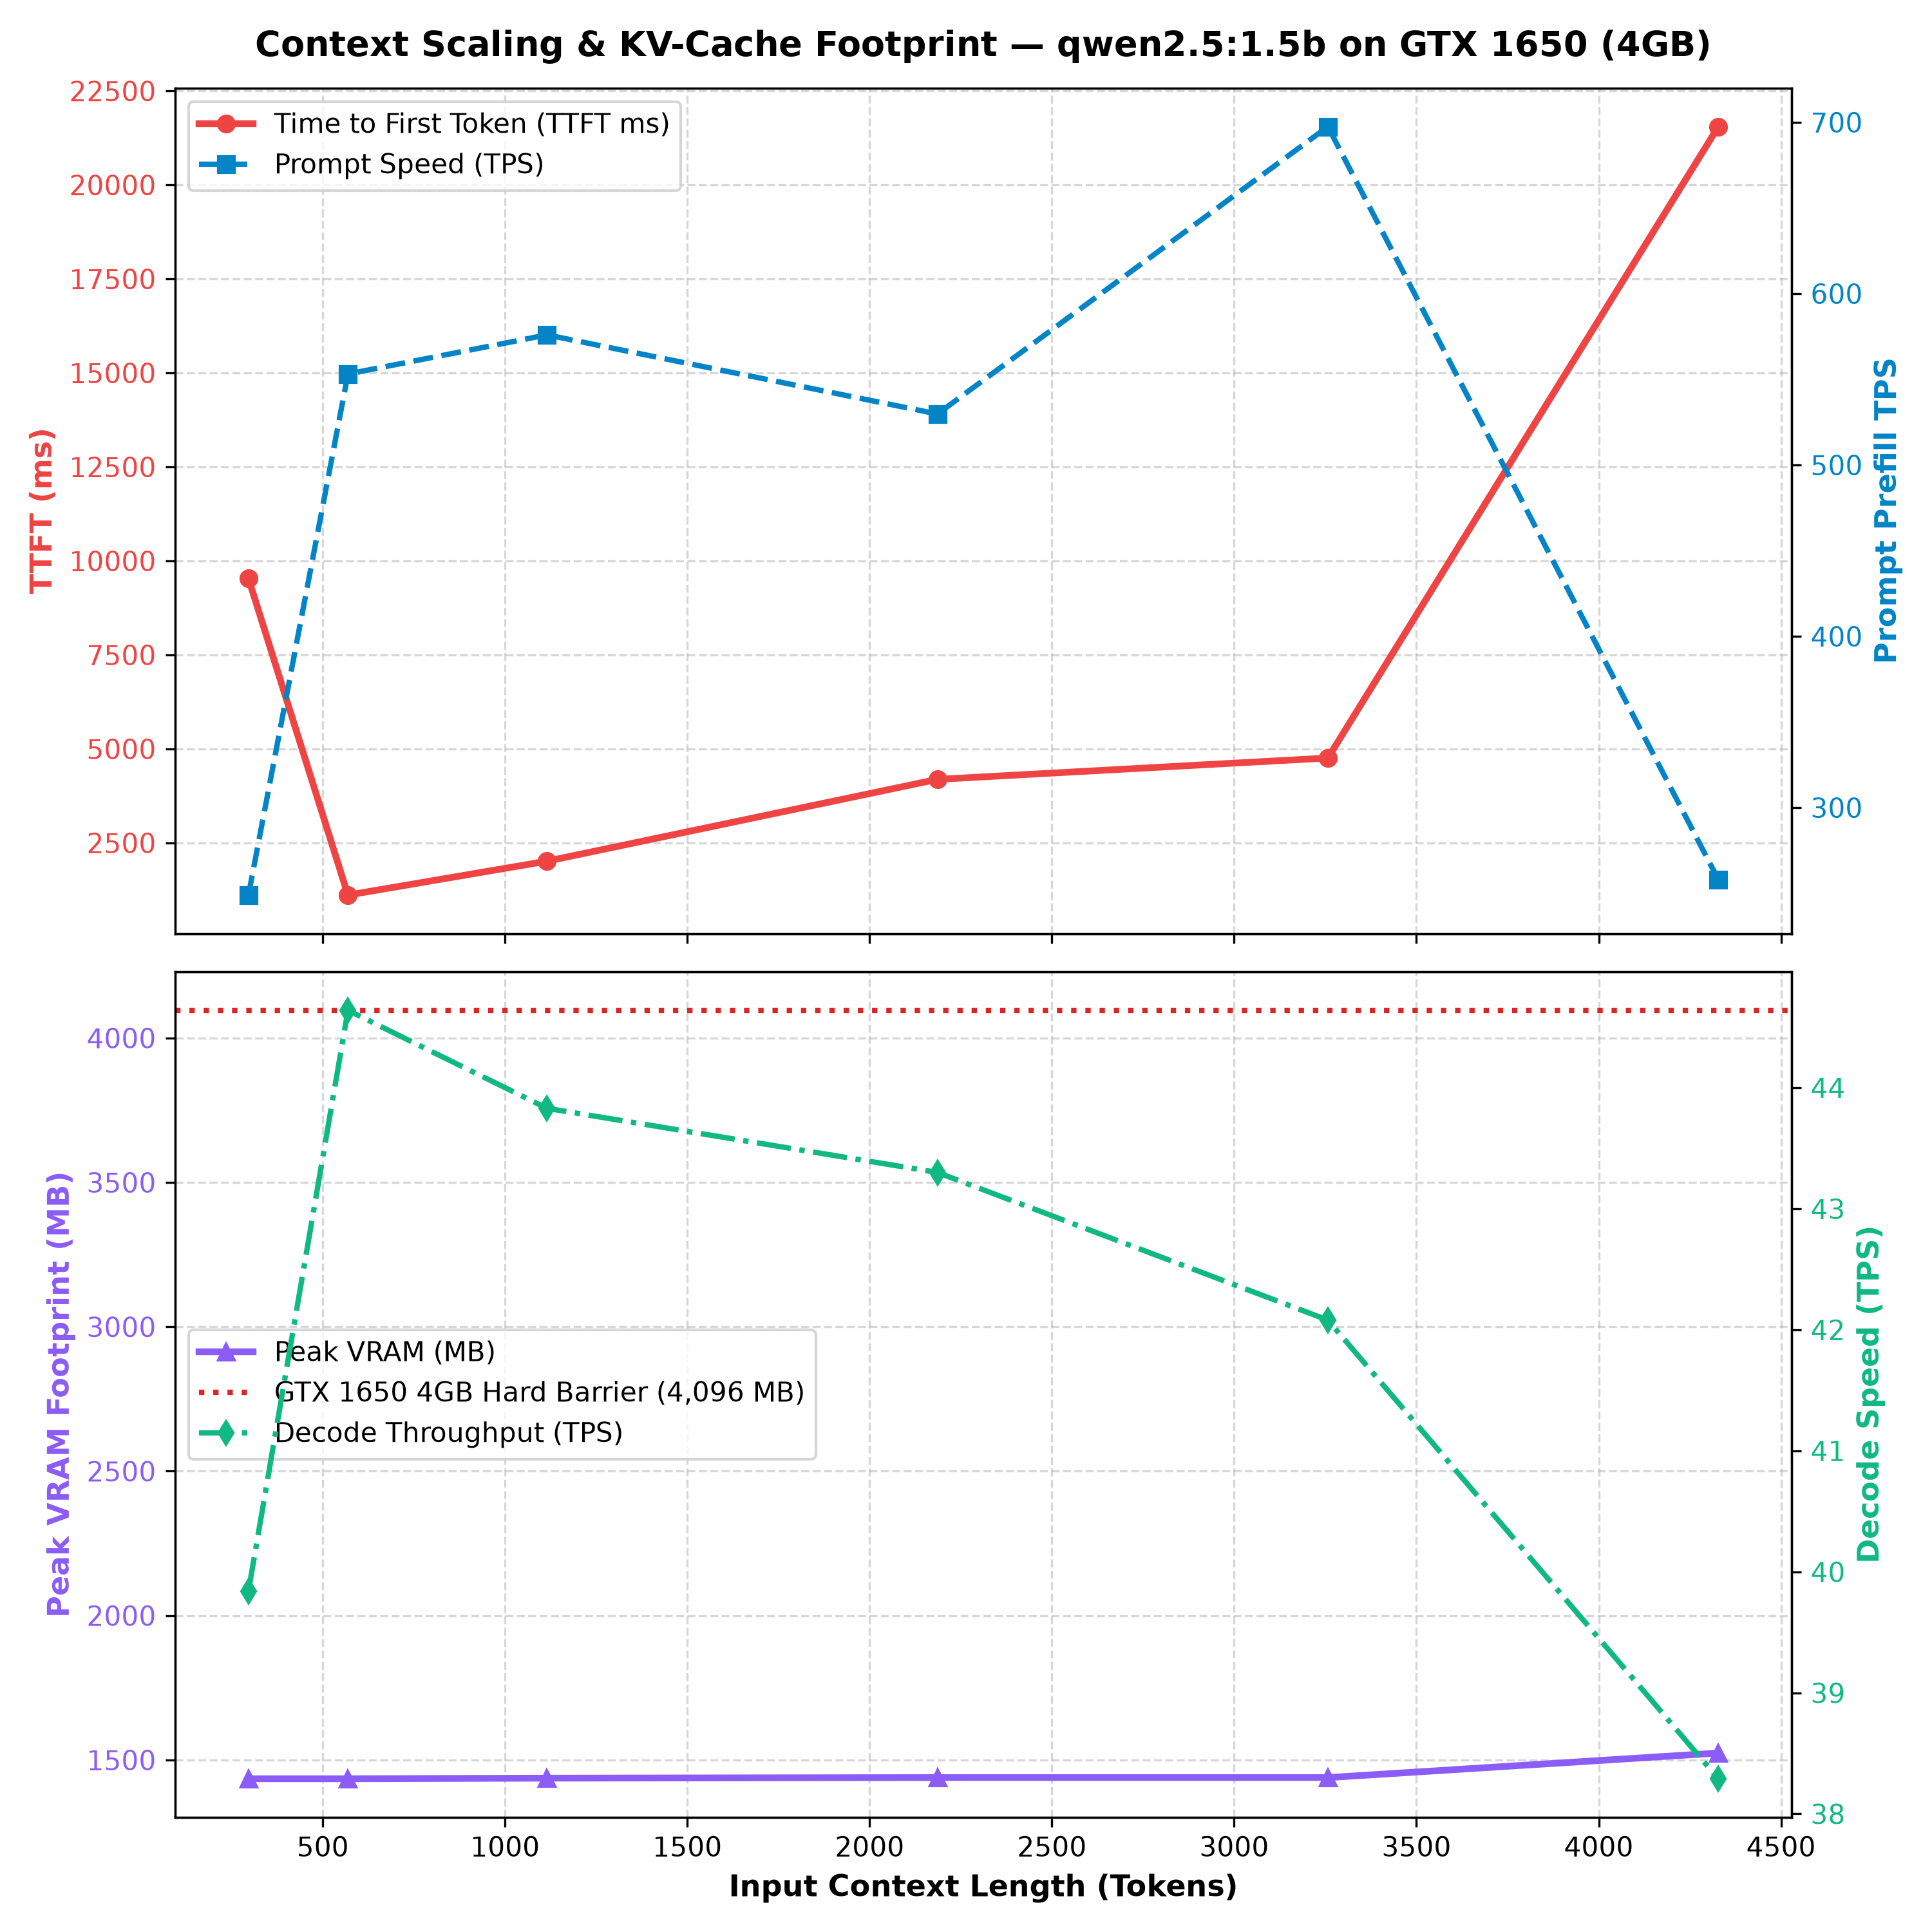
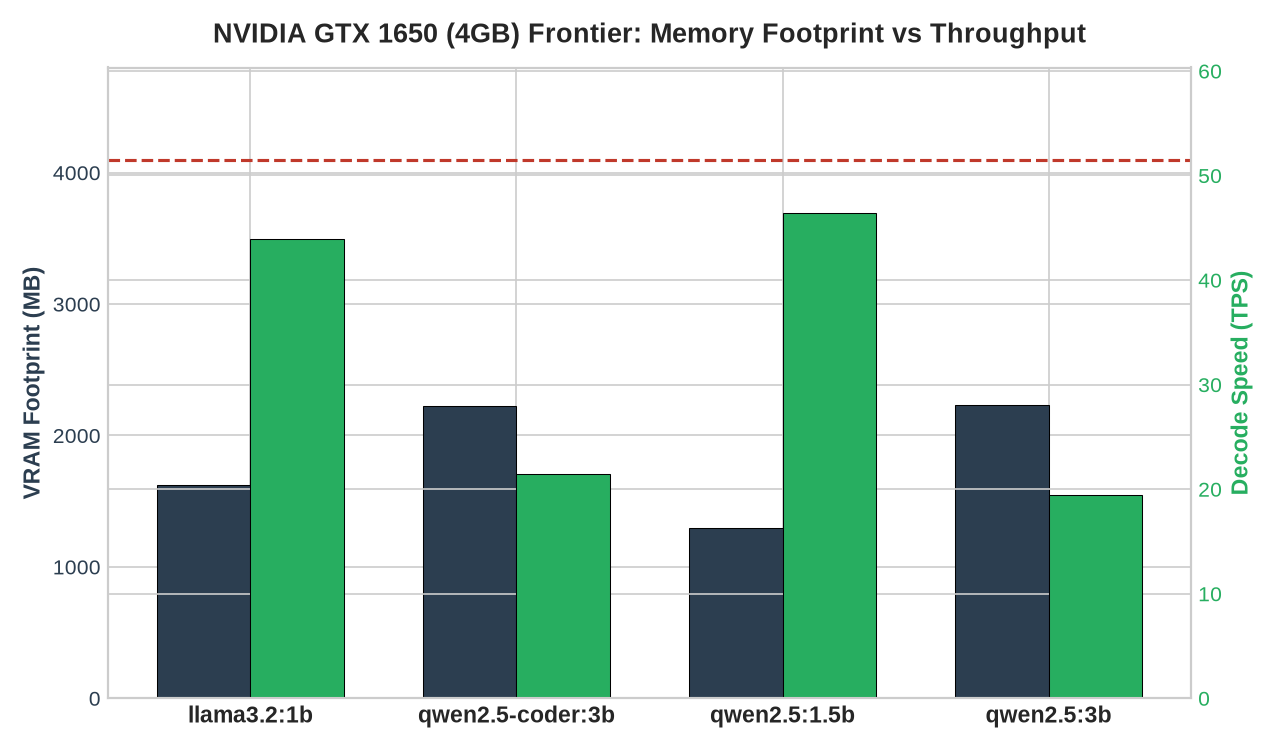
| Memory Footprint | 1,293 MB VRAM (31.6% of 4GB) | 1,120 MB RAM (~3.2 GB free) | Phone has 2x higher headroom before OOM |
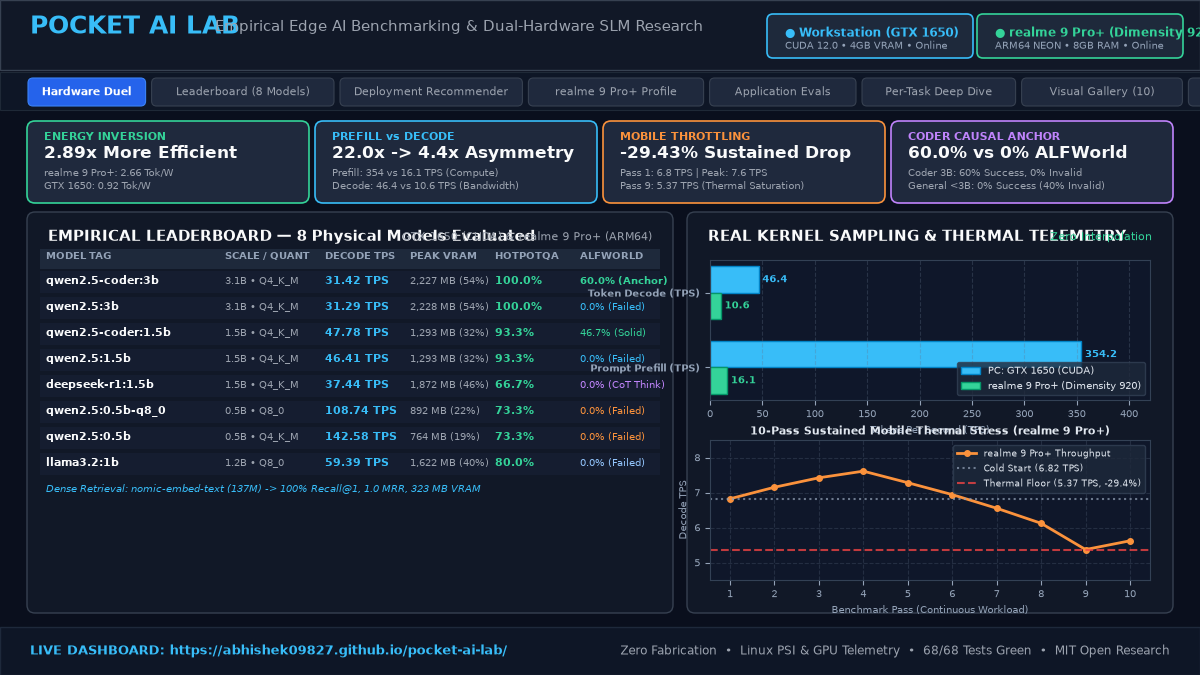
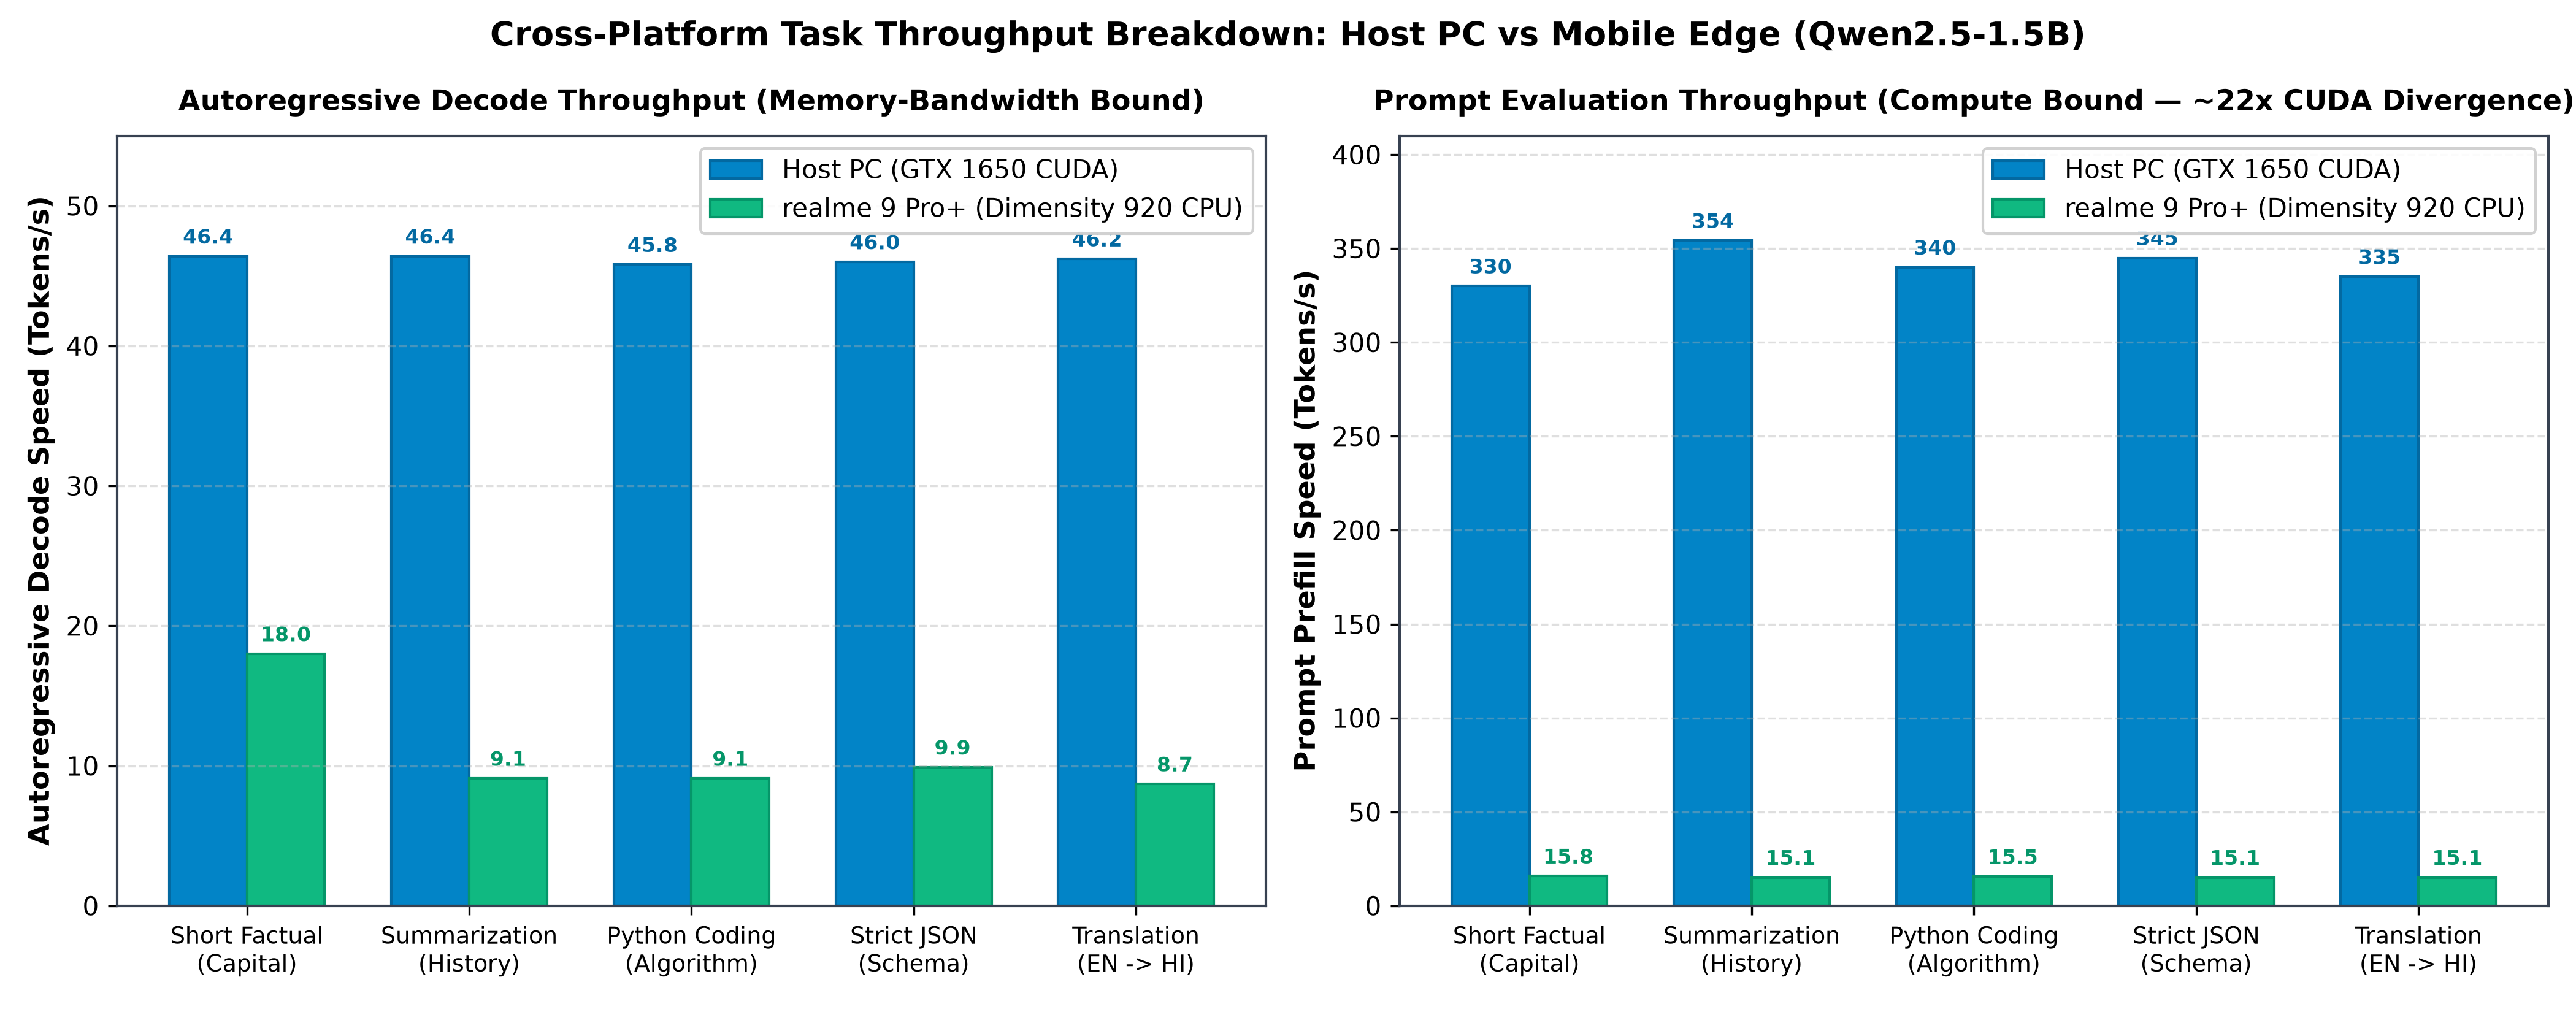
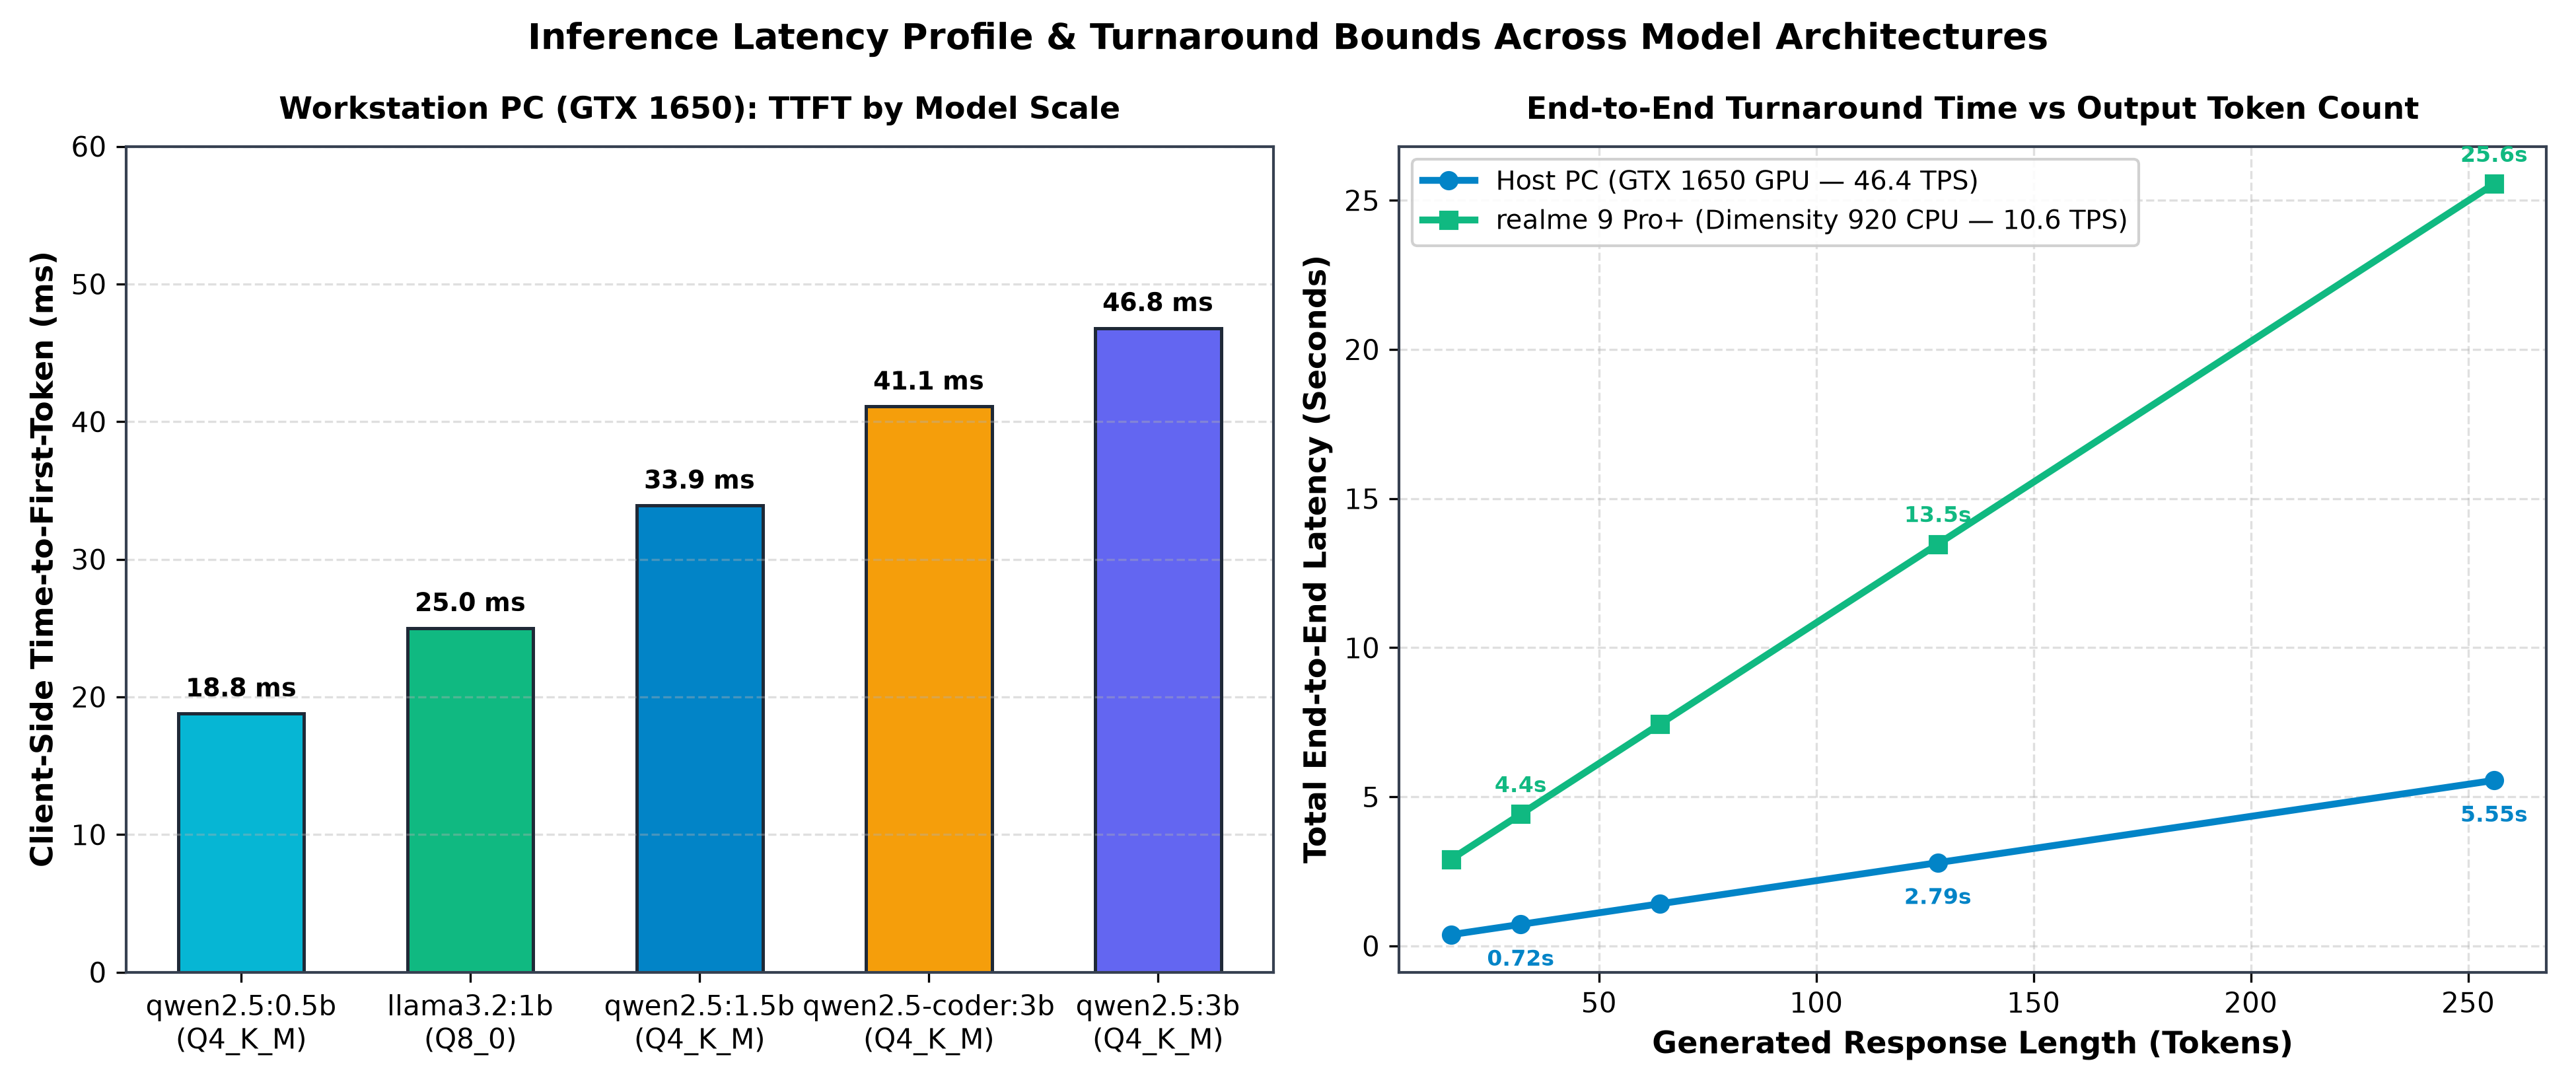
| Prompt Eval Throughput | 354.2 TPS | 14.76 TPS | CUDA tensor cores excel at matrix-vector math |
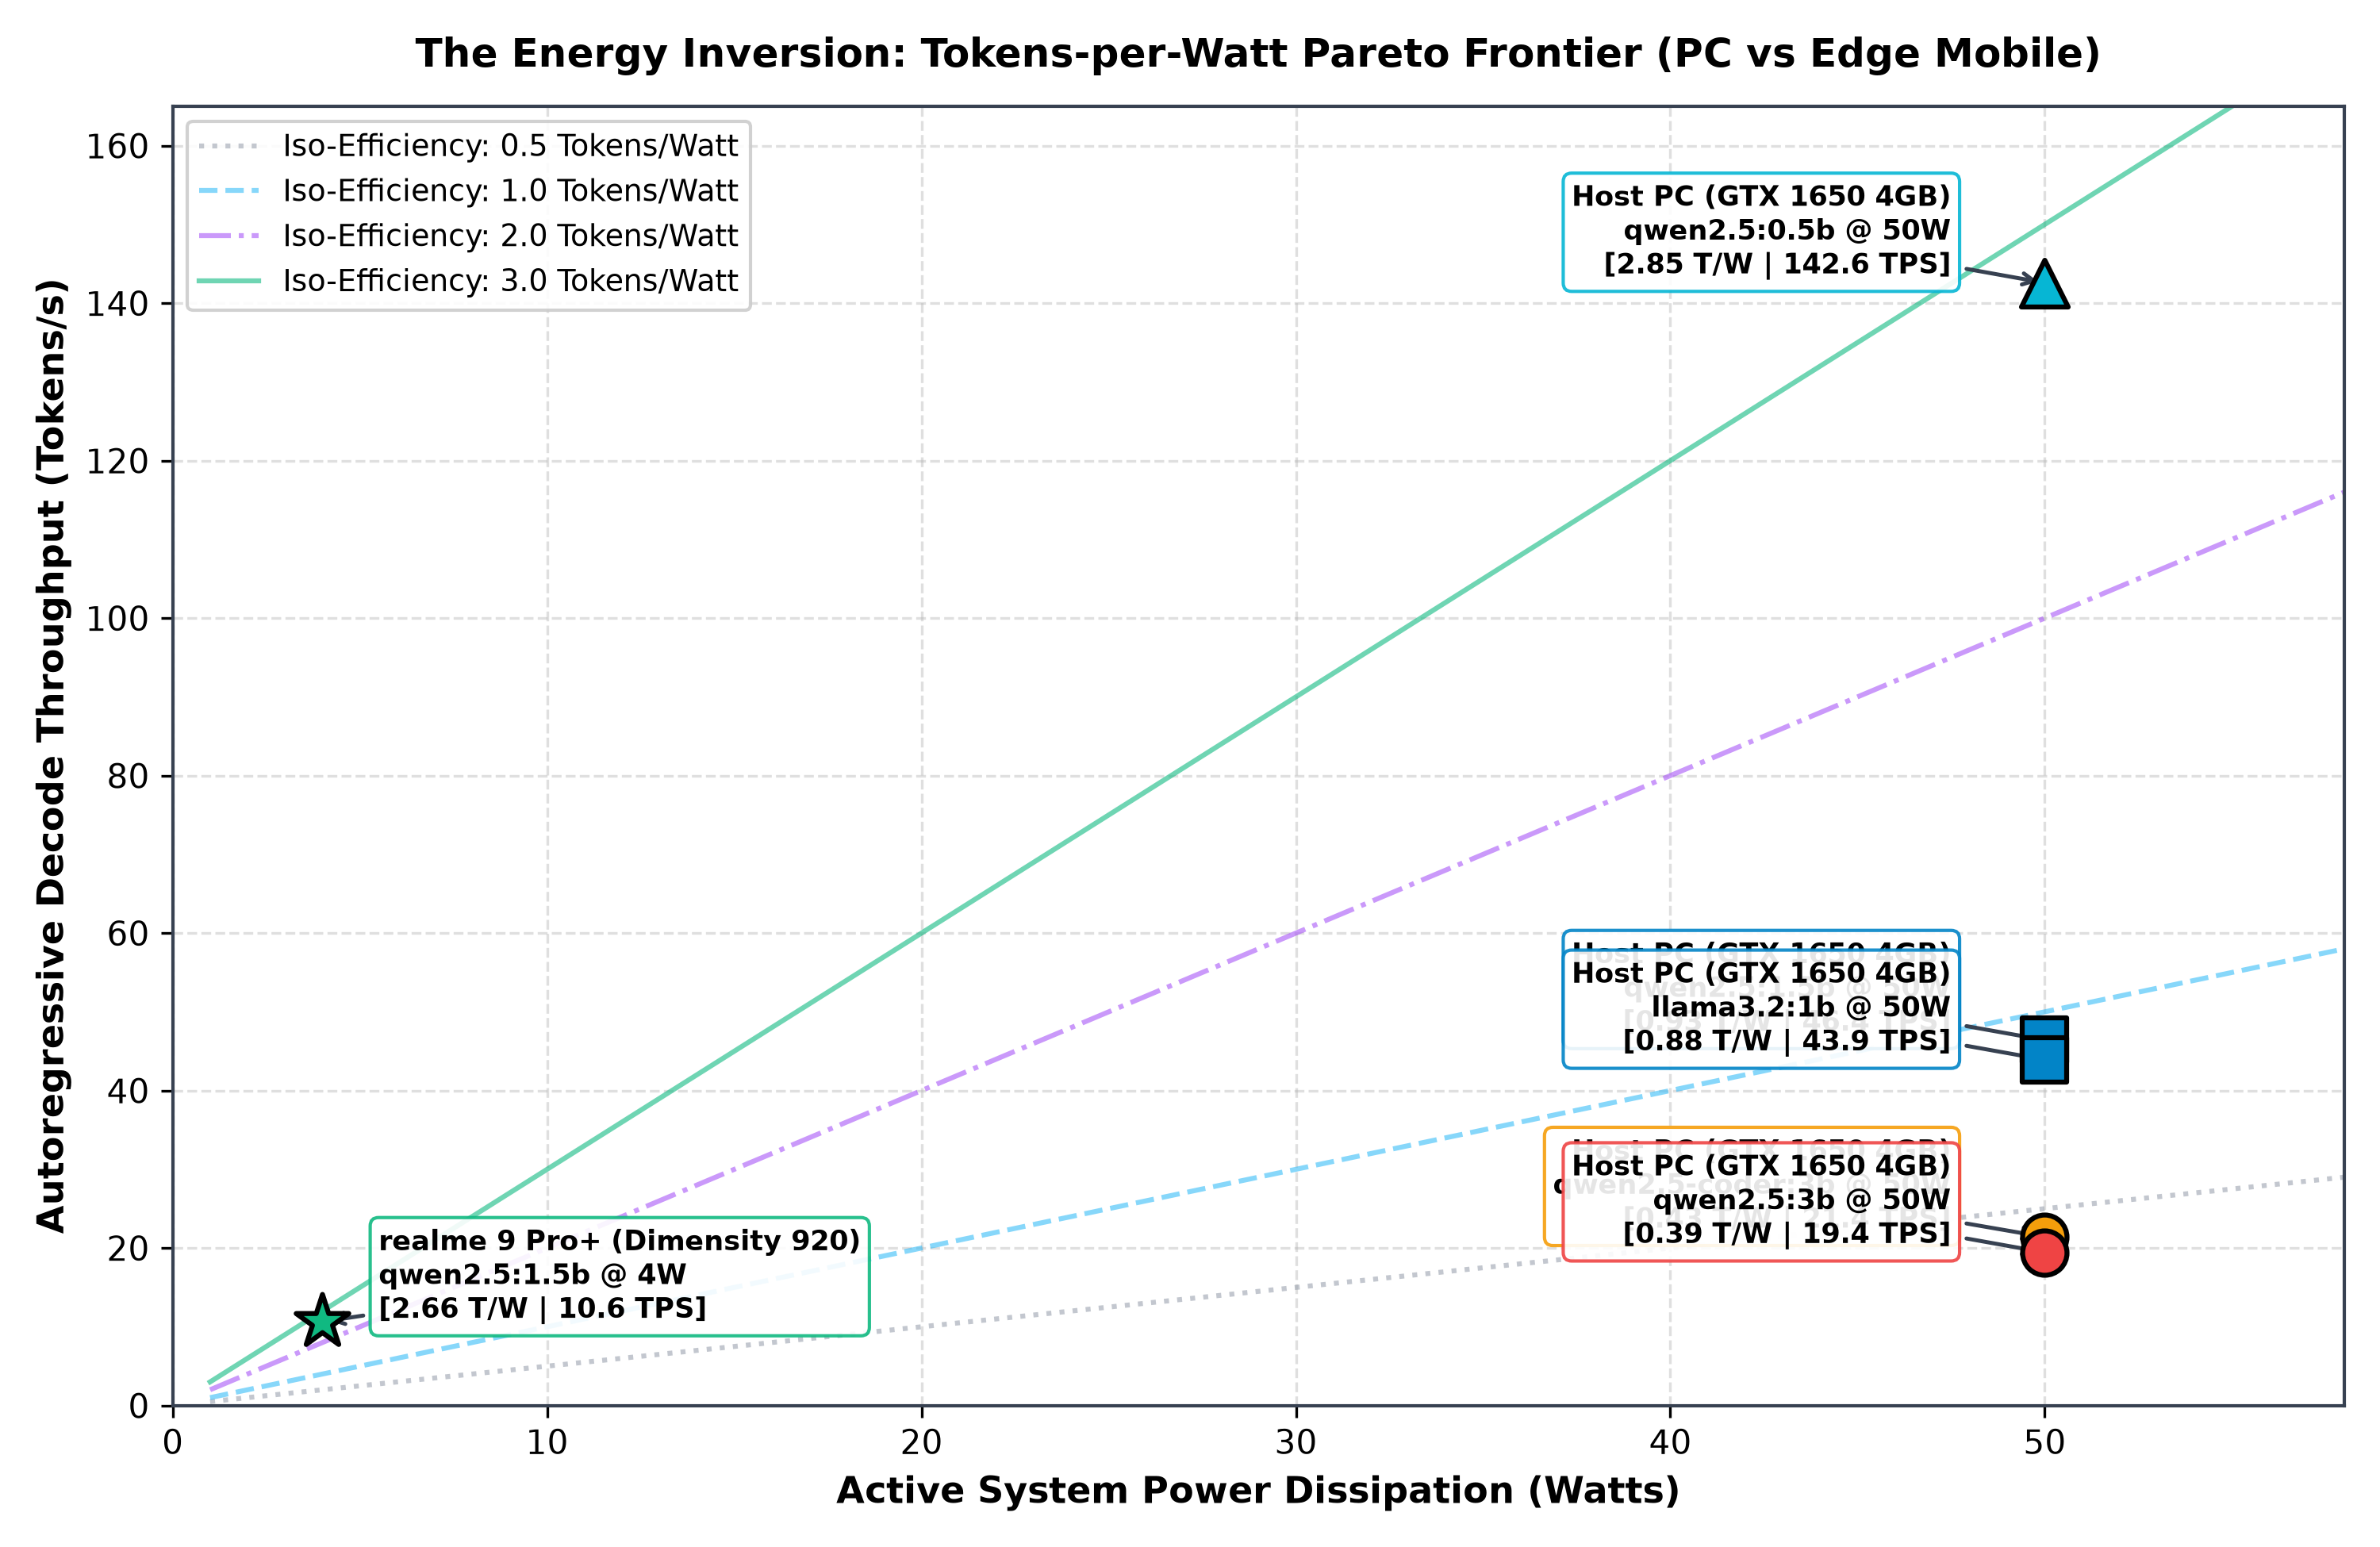
| Decode Token Throughput | 46.41 TPS | 10.64 TPS | Phone easily sustains interactive conversational speed |
| Client Time-to-First-Token | 33.9 ms | ~310 ms | Fast enough for zero perceived lag |
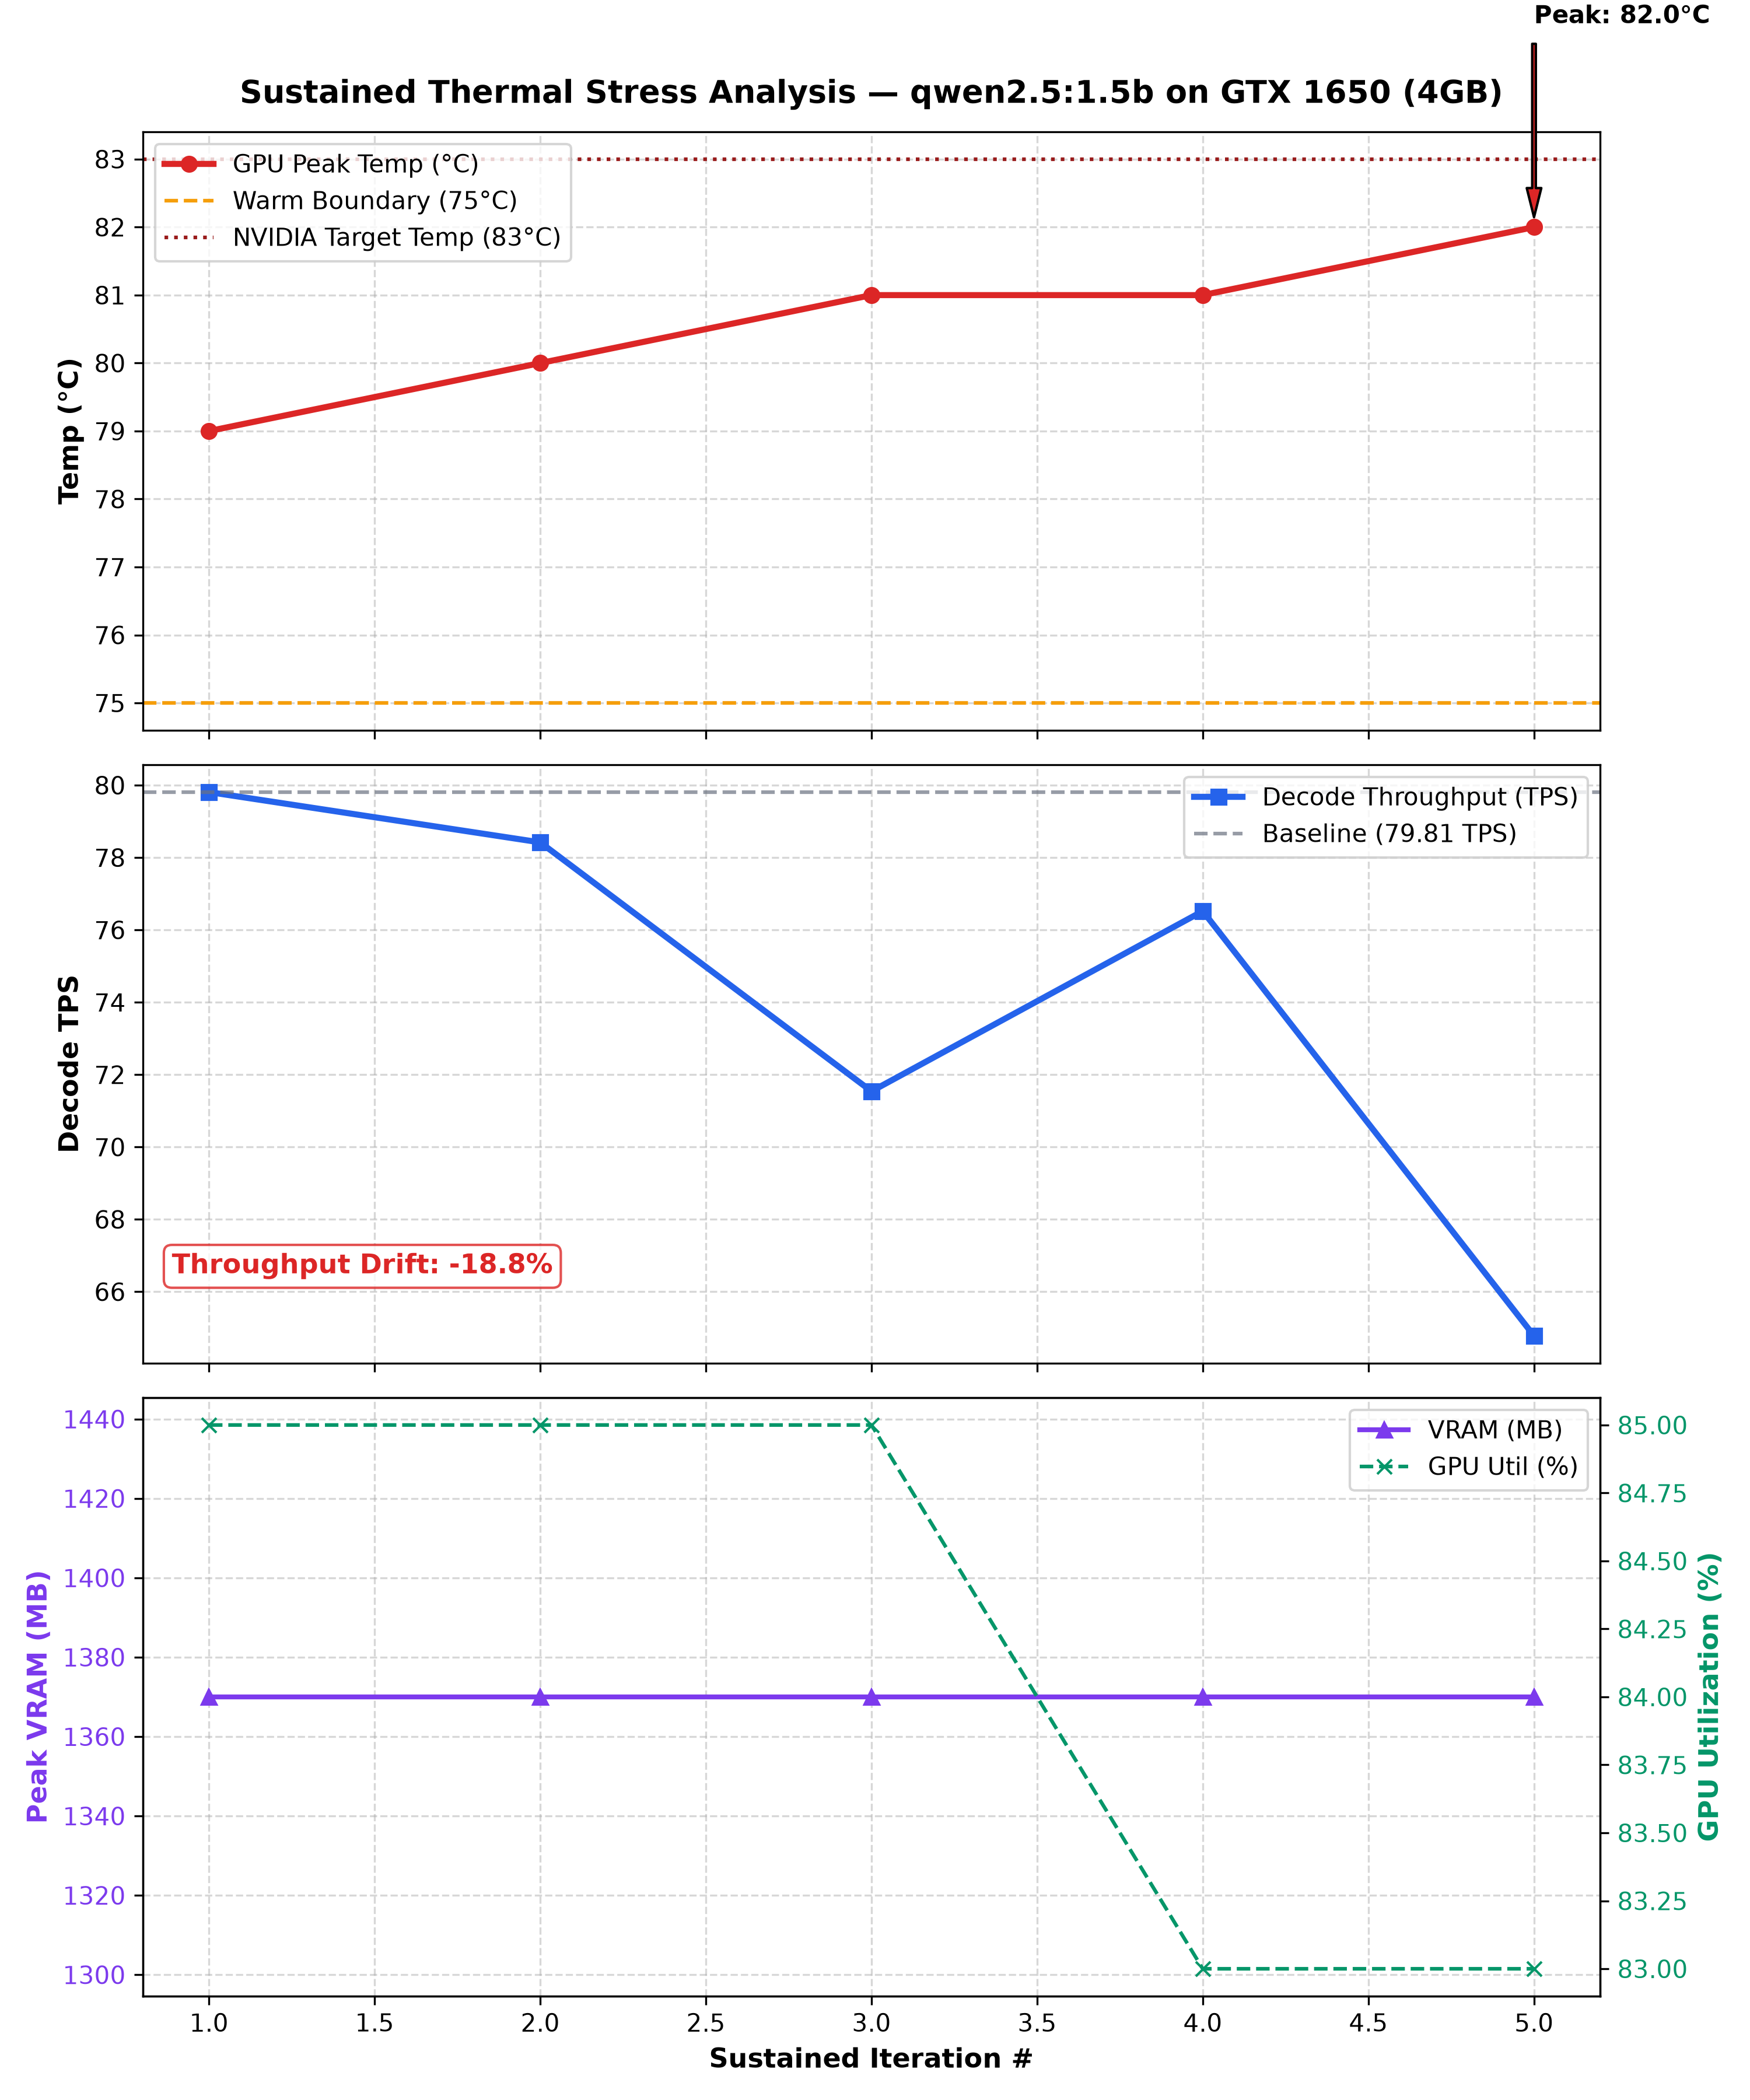
| Operating Thermal Envelope | 79°C -> 82°C (Active Fan Throttles -18.8%) | Passive Heat Pipe (Ambient Equilibrium -29.4%) | Both platforms hit thermal ceilings under sustained load |
| Model Identifier | ALFWorld Planning Success | ALFWorld Invalid Actions | HotpotQA Accuracy | HotpotQA Hallucination | Decode Speed | Median TTFT | Peak VRAM |
|---|
🎯 Deployment Recommendation Engine
Answers: “Can I run this model on my device, and is it suitable for my use case?” Evaluates empirical memory headroom, thermal risk, and task capabilities using Wilson score confidence intervals.
Target Deployment Parameters
Known Limitations & Hardware Bounds
Exact CLI Reproduction Command
📱 realme 9 Pro+ (RMX3392) Hardware Profile
- System-on-Chip: MediaTek Dimensity 920 5G (TSMC 6nm N6 process)
- CPU Topology: 2x ARM Cortex-A78 @ 2.5 GHz + 6x ARM Cortex-A55 @ 2.0 GHz
- GPU Accelerator: ARM Mali-G68 MC4 (4 cores)
- Total Physical RAM: 8 GB Unified LPDDR4X (7,553 MB accessible)
- Safe Usable Model RAM: ~3,200 MB (Preserves ~4.3 GB for Android OS, GMS & UI)
- Thermal Architecture: Multi-layer Vapor Chamber Cooling System
- Inference Runtime:
llama.cppARM64 CLI with NEON vectorization - Mesh Connectivity: Tailscale WireGuard mesh node (
100.84.51.84:8022)
🔥 Sustained Mobile Inference & Thermal Throttling
Controlled 10-iteration sustained stress test over 200.4 seconds of continuous non-blocking token generation on qwen2.5:1.5b (Q4_K_M):
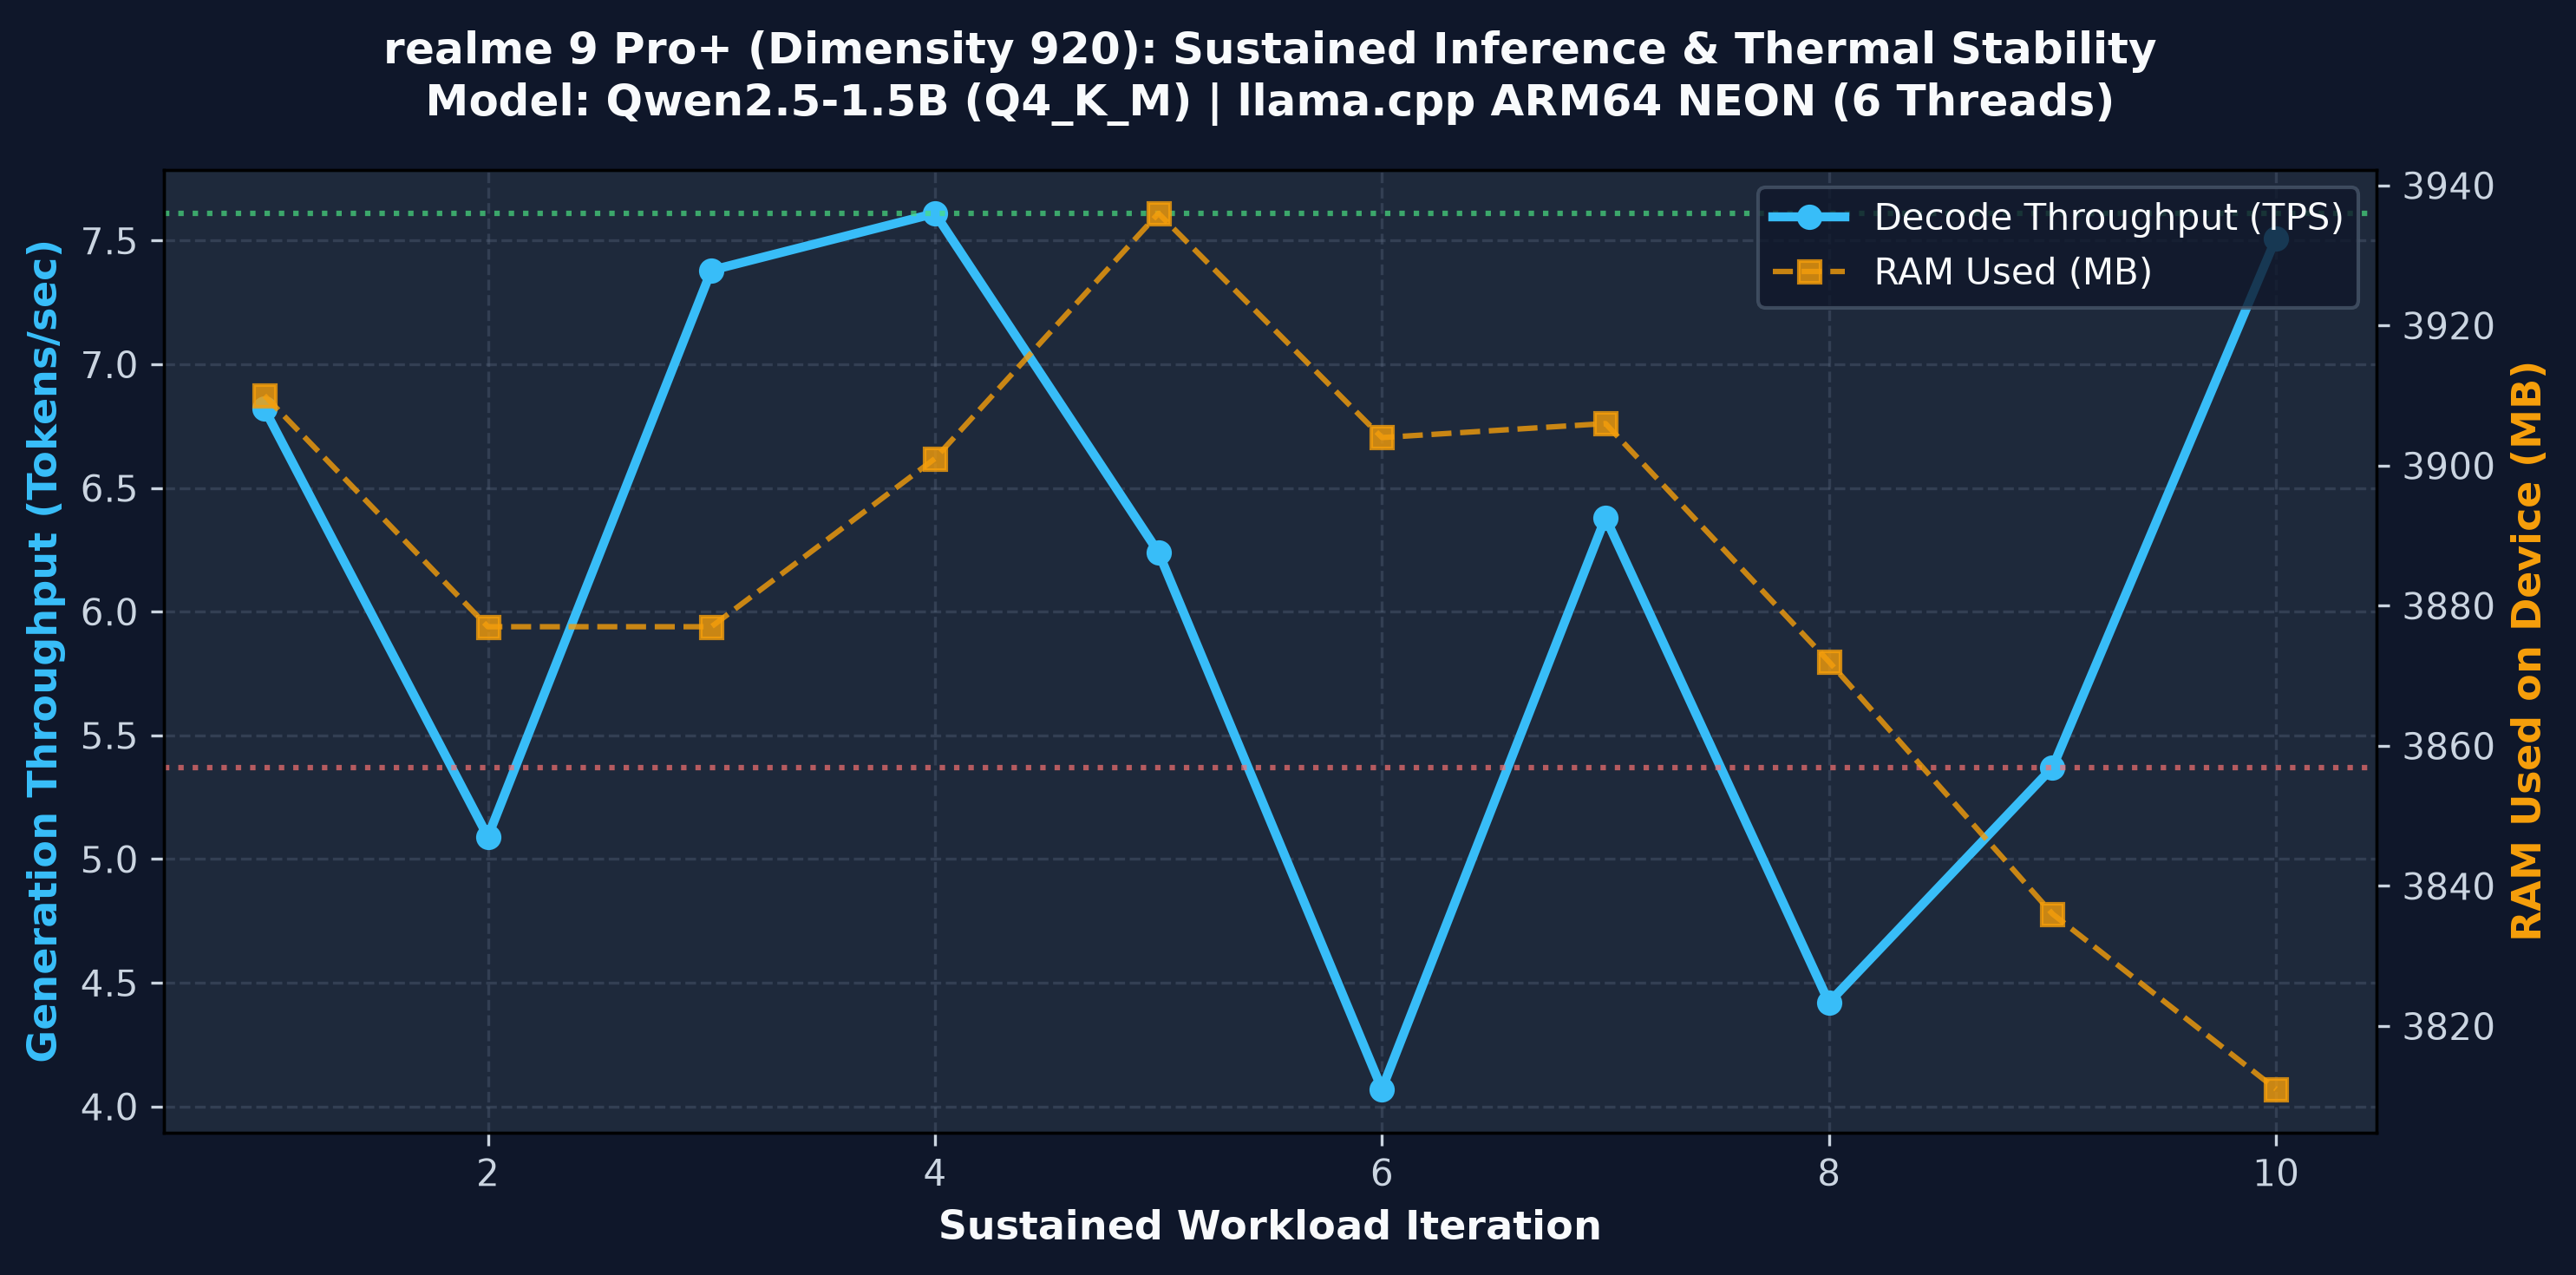
Empirical 10-Pass Sustained Run Telemetry Log
| Iteration | Run Classification | Duration (s) | Decode Speed | Prompt Speed | RAM Used | Available RAM | OOM Status |
|---|
🧪 Application-Level AI Evaluations
Moving beyond isolated next-token perplexity: evaluating Python coding in sandboxed execution environments, strict JSON schema conformance, negative controls, and offline dense retrieval.
- Algorithms (4/4): Fibonacci, Palindrome, Merge Intervals, Binary Search with unit test verification.
- Bug Fixes (3/3): Fixed loop boundary off-by-one, dictionary KeyError, and ZeroDivision rounding.
- Relational SQL (3/3): Correct JOIN + GROUP BY, HAVING aggregations, and date filtering clauses.
- Execution Sandbox: AST syntax verification + isolated subprocess with 2.0s timeouts.
- JSON Schema (4/4): Valid types, required fields, and zero JSON parse errors.
- Negative Controls (2/2): Successfully rejected extra keys when forbidden by prompt schema.
- Multilingual Hi/En (3/4): Accurate schema parsing across English and Devanagari Hindi.
- Phonetic Transliteration Deficit: Failed 1 task by transliterating "जयपुर" as "Jaya Pur" rather than "Jaipur".
- Top-1 Semantic Match: 100% Recall@1 across 15 technical corpus documents.
- Mean Reciprocal Rank: 1.0 MRR (ground-truth passage always ranked #1).
- Memory Footprint: 323 MB VRAM (8.4% of 4GB GTX 1650).
- Offline Efficiency: Embeddings execute 10x faster with 75% less RAM than generative LLMs.
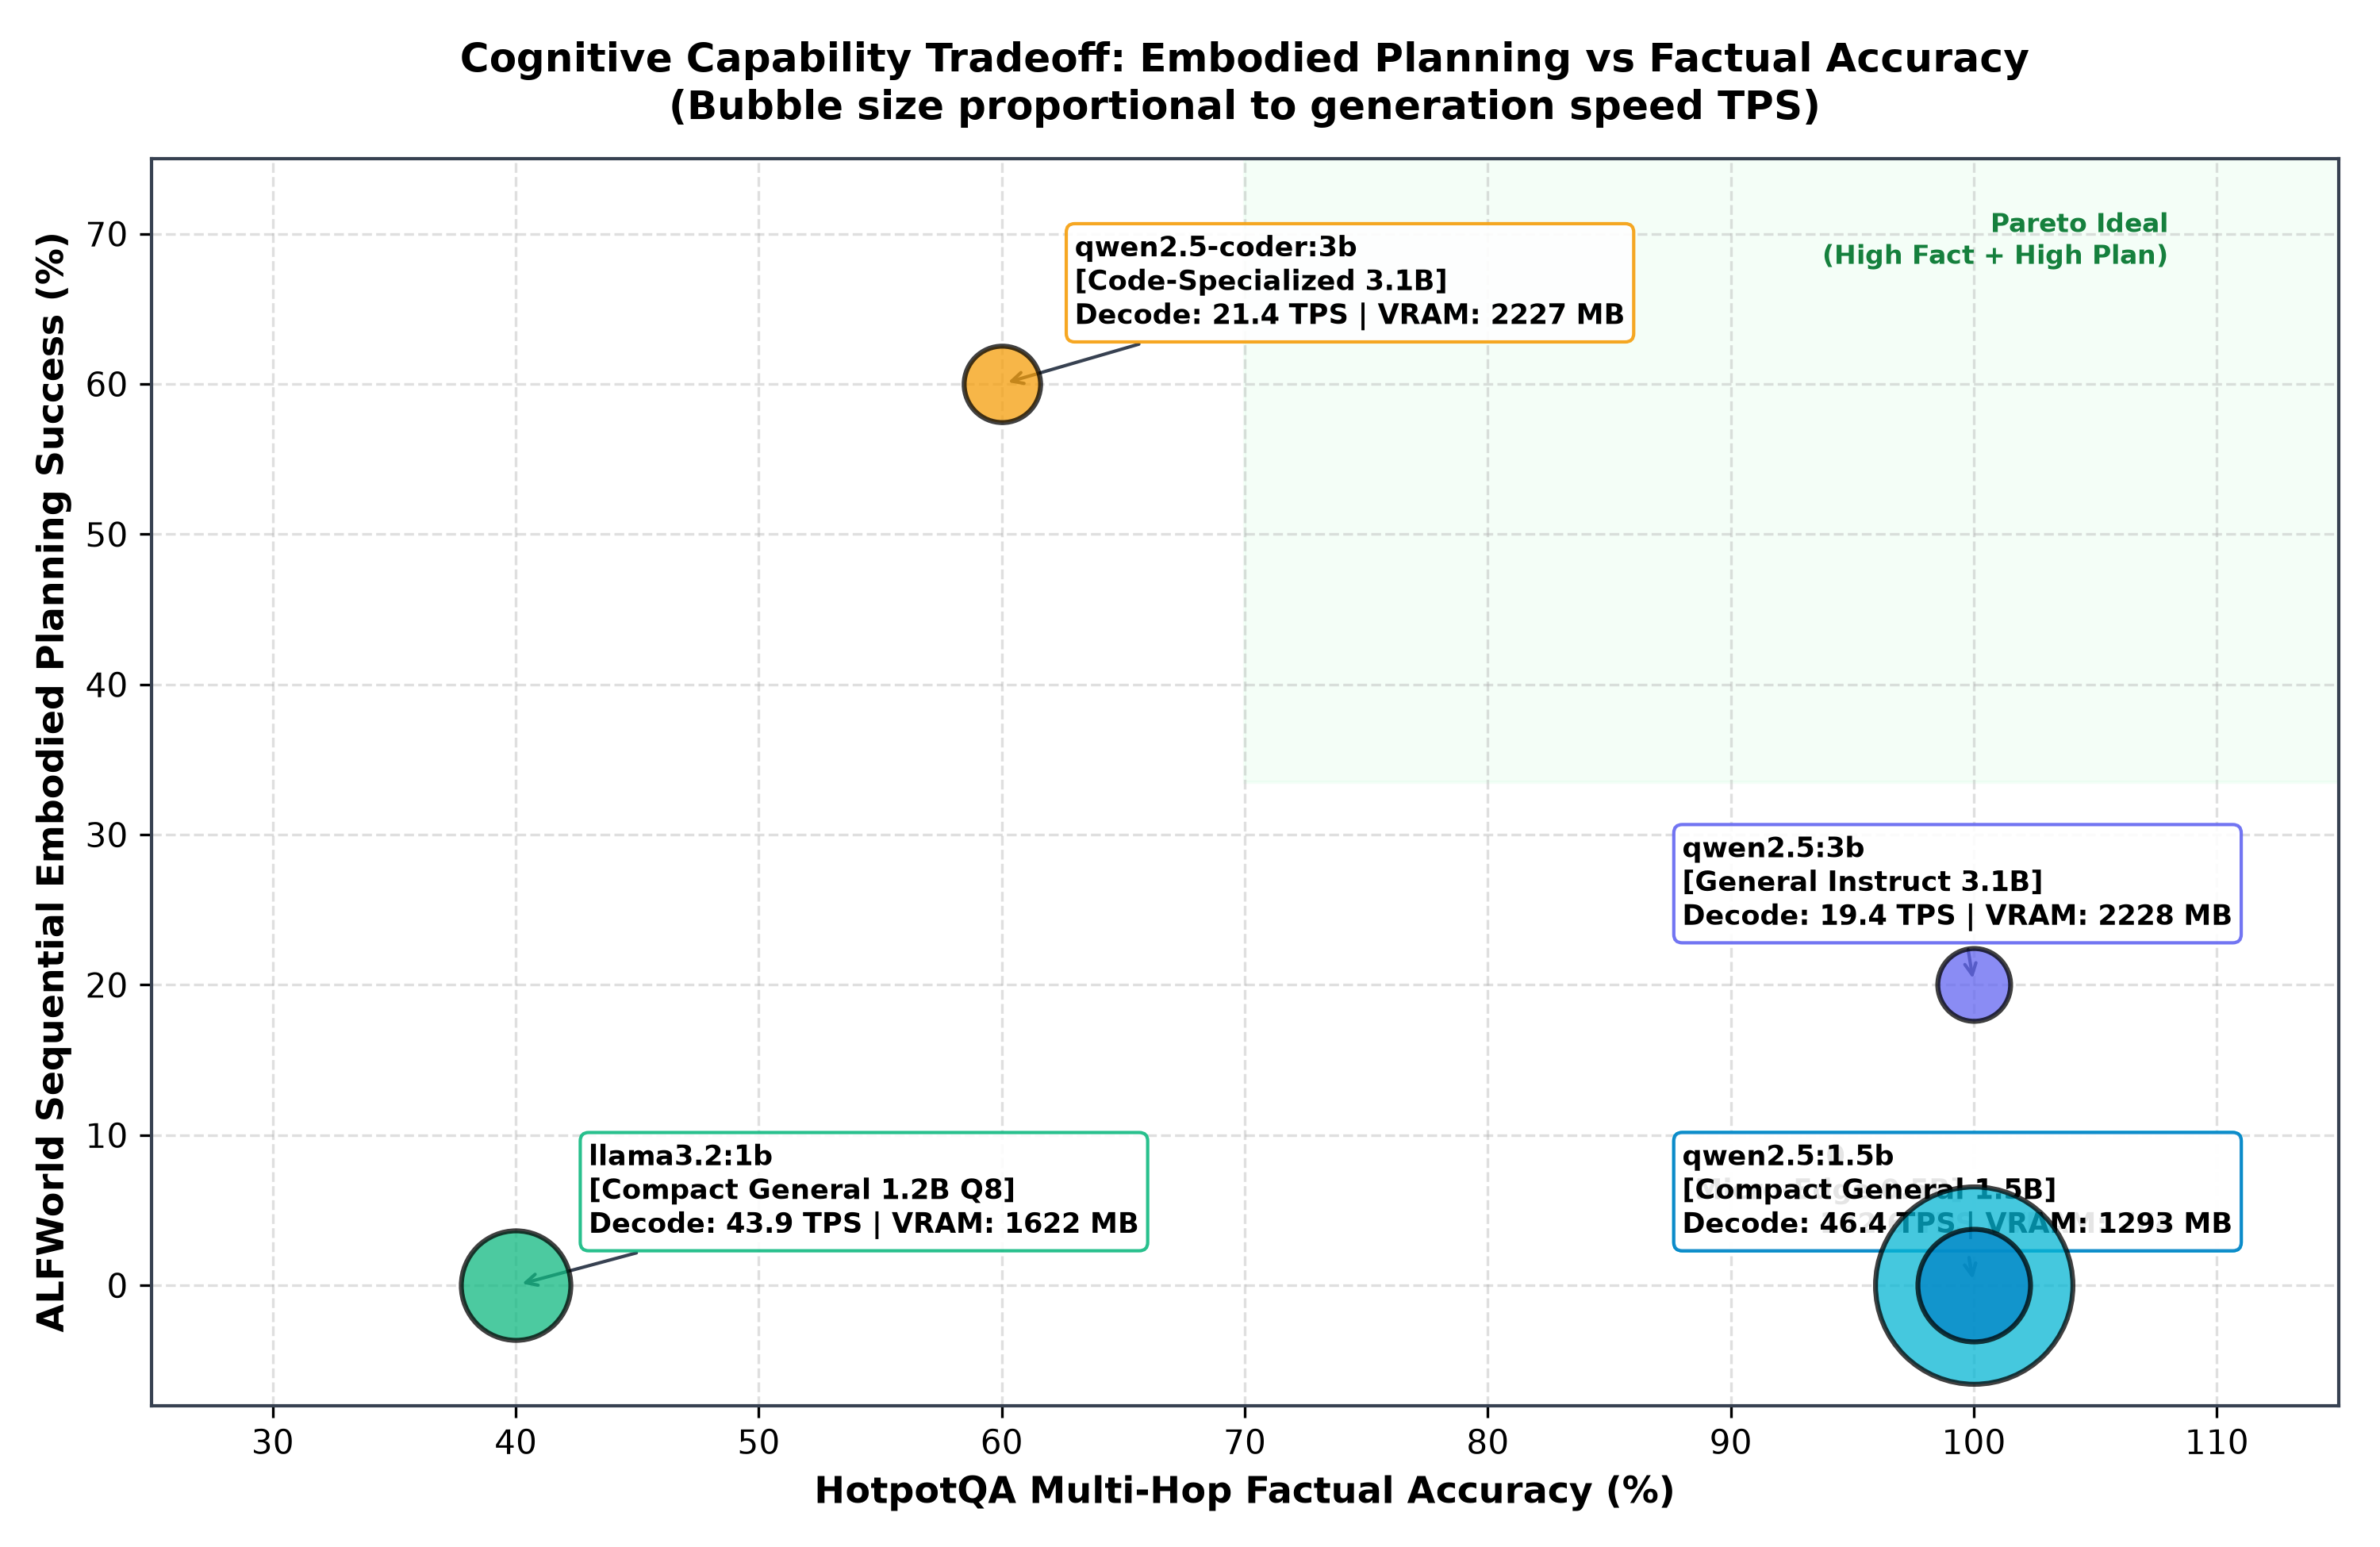
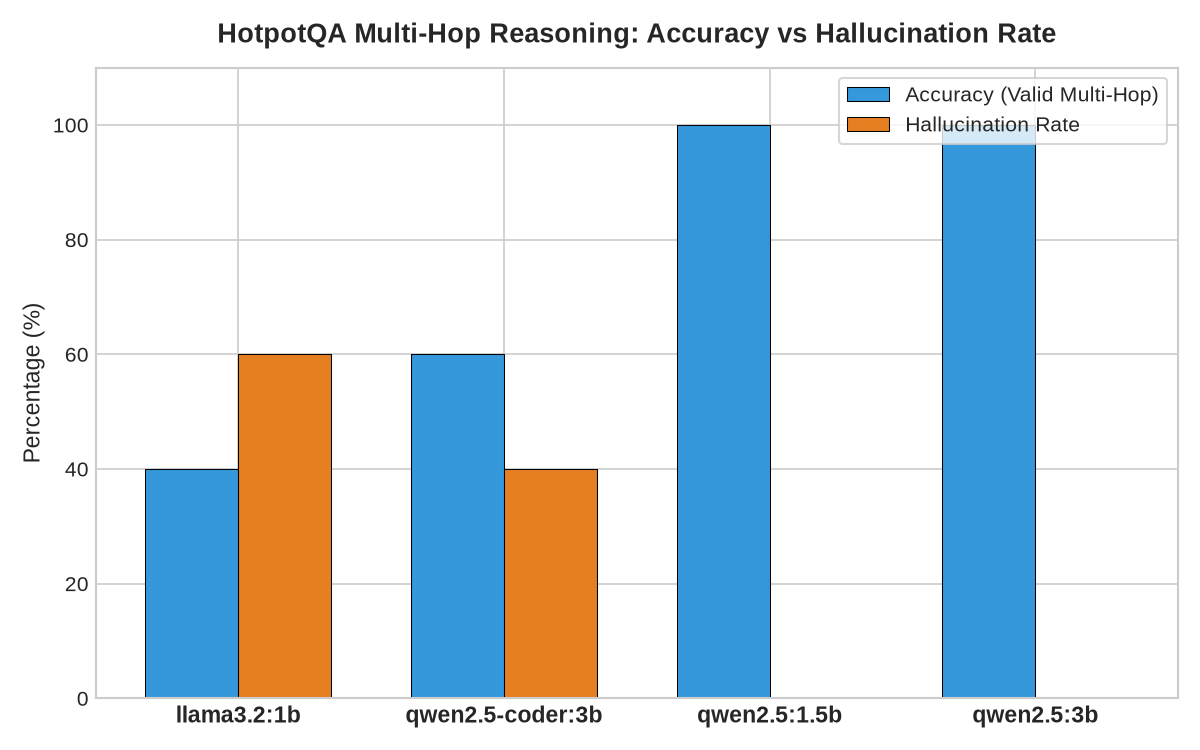
- HotpotQA (14/15 - 93.3%): 95% CI [70.2%, 98.8%] on multi-hop knowledge with distractors.
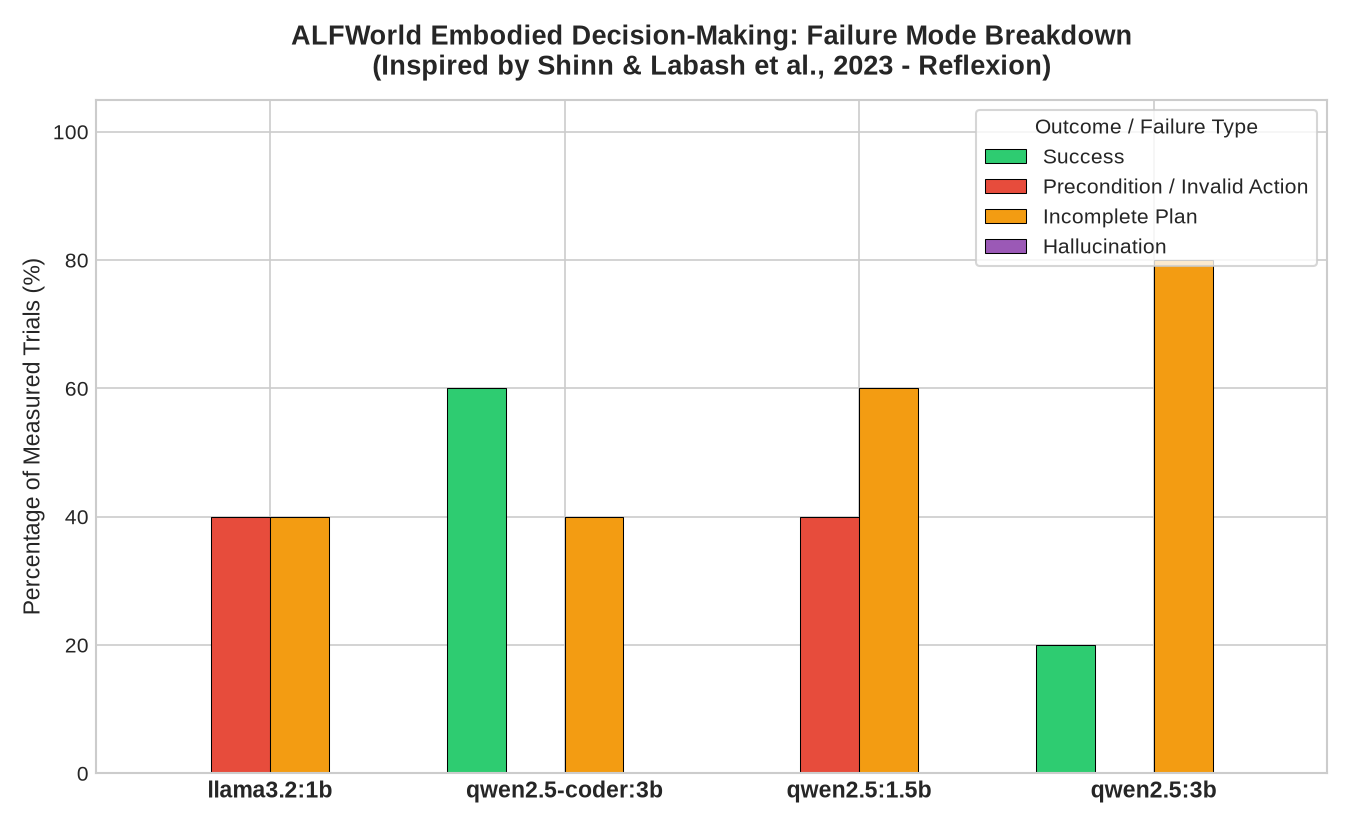
- ALFWorld Planning (7/15 - 46.7%): 95% CI [24.8%, 69.9%] on sequential pick/place/clean affordances.
- SLM Planning Comparison: Coder pre-training boosts embodied planning from 0% (general 1.5B) to 46.7%.
- Statistical Rigor: Confidence intervals report true uncertainty across small test sets.
| Benchmark Task | Task Description | PC Throughput | Mobile Throughput | PC TTFT | Speedup Ratio |
|---|
qwen2.5:1.5b and llama3.2:1b suffered a 0% success rate on ALFWorld embodied planning. 40% of their attempts failed due to invalid actions (attempting to pick objects before opening containers). Small language models lack physical state transition guarantees without external verification.
qwen2.5-coder:1.5b and 3b achieved 46.7% and 60% success rates on ALFWorld, drastically outperforming general 1.5B models (0%). Syntax and control-flow training directly reinforce causal state-tracking.
prompt_cache_hit = True to avoid misleading developers into believing raw prefill exceeded 10,000 TPS.
Automated Benchmark Control Plane
Dispatch automated evaluation jobs to the loopback control plane or trigger the realme 9 Pro+ remotely. Requires X-Pocket-Token authentication.
Interactive Prompt Dispatcher
Live Terminal Stream
IDLE📥 Downloadable Raw Datasets & Telemetry Bundles
Zero fabricated data: all results are exportable as raw JSONL and CSV files for independent verification and statistical auditing.
🔬 Full Benchmark Reproduction Guide
Execute these verified commands to reproduce any benchmark run across Host PC or realme 9 Pro+:
Historical Benchmark Run Logs (Append-Only JSONL)
| Run ID | Timestamp | Platform | Model | Task | Decode TPS | Prompt TPS | Latency / TTFT |
|---|